
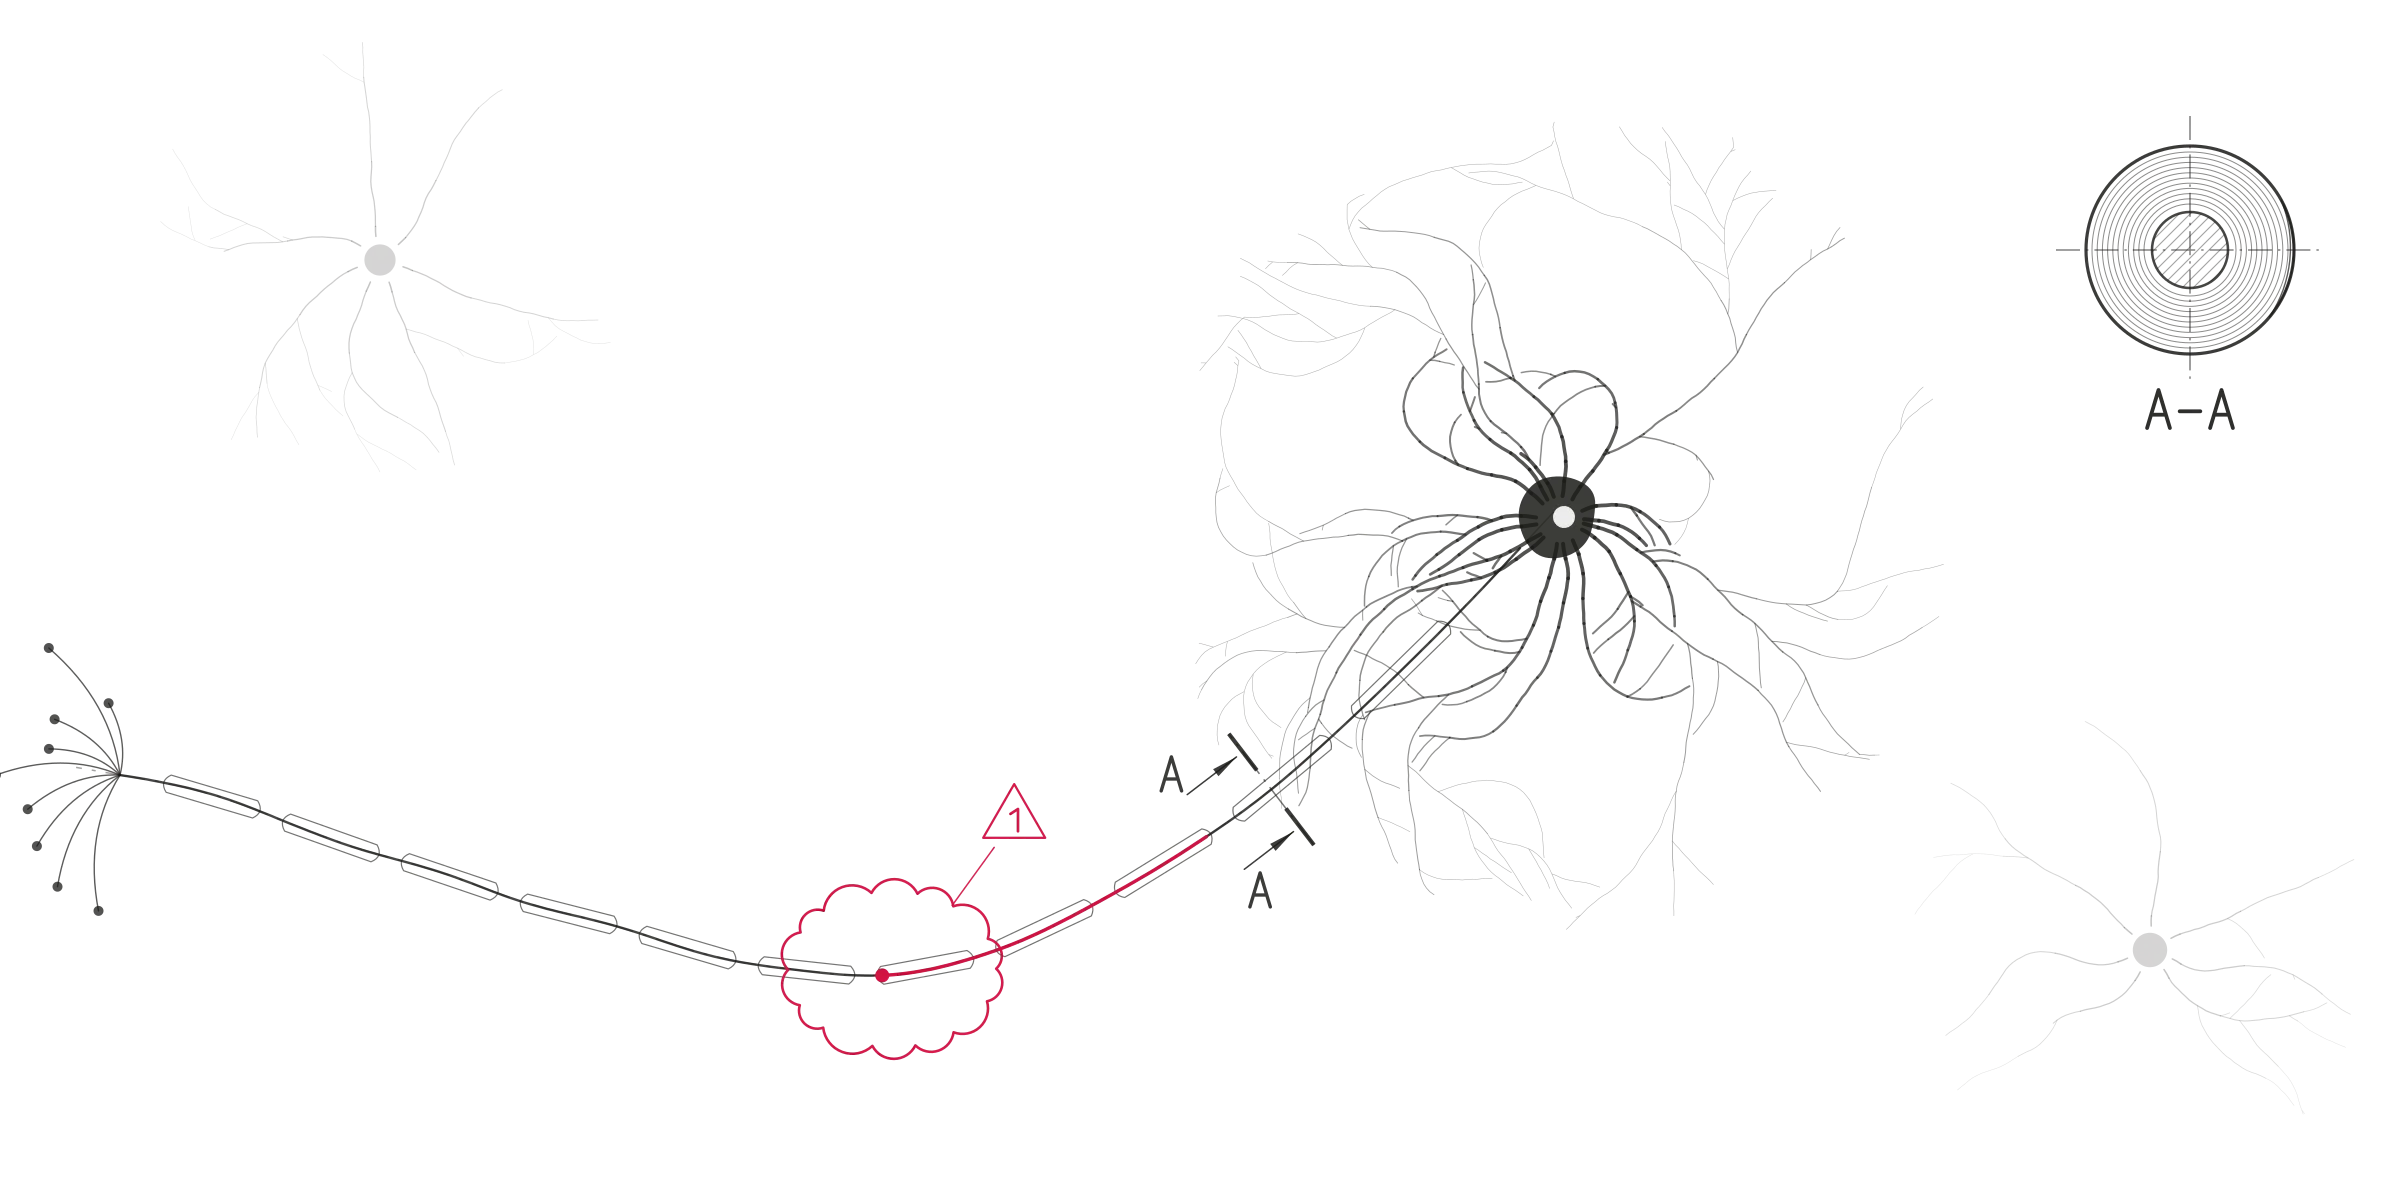
Your projects get a nervous system, built the way living ones are.
A language model forgets everything once a conversation ends. Nervous systems solve that in layers, from senses that never switch off to a memory that finds the right moment, and AUVY is built from the same layers with a person deciding at the top. Unlike a brain, it keeps every word.
A whole nervous system
The whole system first, in the real project.
In 1991 the roboticist Rodney Brooks argued for building complete systems that act in the real world from the start, in layers that each work on their own and grow more capable over time. Nervous systems grew that way, and AUVY is built that way.
- SensesMail and file changes land here first, and each one is read, dated and filed to its project as it arrives.
- MemoryEverything the project received is kept word for word with its source, and a question can reach it by date, by person or by what was meant.
- Prepared stepsWhen something changes, AUVY works out what it affects and drafts the next step, such as a reply to the client or a new date in the plan.
- A person decidesEvery draft stops here until someone accepts, edits or rejects it, and only then does it leave.
How it finds
What the brain does to find a memory, and what AUVY takes from it.
Your brain drops most of the detail but finds the one thing you need from a date, a place, a name or half a sentence. Each ring is one process that memory research describes and what AUVY builds from it, while keeping the detail the brain would lose.
- One fact, one trace
In the brain: Two similar meetings stay two memories. You do not get a blur of both.
In AUVY: Mails and files are split into pieces of one fact each, so a search lands on the passage that holds it.
- When and where
In the brain: You often find a memory through the day or the room it happened in.
In AUVY: Every passage knows its date and folder, so a question about last week or one folder is searched there first.
- People and relations
In the brain: You know who works with whom without remembering where you learned it.
In AUVY: AUVY maps people, companies and meetings from what it reads, each link backed by the sentence that states it, and a question about someone follows those links.
- From a fragment to the whole
In the brain: A smell or a phrase can bring back the whole scene.
In AUVY: When a search finds one passage, AUVY also reads the section or thread around it, so the answer has the whole conversation behind it.
- Filing it overnight
In the brain: While you sleep, the brain goes back over the day and files what mattered.
In AUVY: In the background, AUVY turns new mail and meeting notes into short facts and summaries that a search can find, each linked to the original.
- The newer fact first
In the brain: When you learn that something changed, the new version takes the old one's place.
In AUVY: When a date or a price changes, the latest statement comes first and the old one stays on record, marked by the red cloud on the drawing.
- What comes to mind first
In the brain: What you use often comes to mind first, and what you never use fades.
In AUVY: Passages nobody uses rank a little lower when two are otherwise equal, but none are deleted.
- Knowing what you don't know
In the brain: You can tell when you do not know something, and you say so.
In AUVY: When the sources do not hold the answer, AUVY says it did not find it, and marks any sentence it cannot back with a source.
- Beyond memory
In the brain: Memory is one of several things the brain does to act well.
In AUVY: We plan to take the same approach to attention, prediction and planning.
Results
Four public benchmarks, no outside model in the search.
They test whether the right passage turns up in a long history and whether the answer drawn from it is correct. The benchmarks use chat histories where AUVY reads project mail and files, but the task is the same.
| Benchmark | What it tests | Count | AUVY | Other systems |
|---|---|---|---|---|
| Finding | ||||
| LongMemEval-S | Find the conversation that holds the answer, among about 50 per question | 500 | 99.4Highest score |
|
| LoCoMo | Find the session that holds the answer, in ten conversations that each ran for months | 1,540 | 94.9 | – |
| Answering | ||||
| MemConflict | Answer when stored facts contradict each other | 3,750 | 70.4Highest score |
|
| LongMemEval-S | Answer from about 115,000 tokens of chat history | 500 | 91.8 |
|
| LoCoMo | Answer about the same ten conversations | 1,540 | 91.8 |
|
| BEAM 1M | Ten memory abilities over conversations of about a million tokens | 700 | 62.4 |
|
Finding: the right source in the top five results. Answering: share correct, judged the way the other systems report it: LongMemEval with its own judge prompts, LoCoMo with Mem0's published prompt, MemConflict as the average over its three conflict types. BEAM: nugget score from 0 to 100, Mem0's judge prompt; the rest in percent. Other systems as they publish them, each with its own answer model; a dash where nobody publishes the same measure.
Open problems
What we are working on next.
- Every source, not just one
- Search almost always finds one source an answer needs, but not always every one. Questions that combine several conversations lose most. Filing it overnight is aimed at this.
- Time and change
- Questions about the newer of two facts, about time and about the order of events score lowest, and so do facts that should not have changed. The newer fact first is aimed at this.
Method
How the numbers were made.
- What ran
- AUVY's document store and search ran on a separate benchmark stack with no customer data, with its own workspace and index for each benchmark. Each benchmark and model ran once in full, and every question counts, with none dropped or retried.
- Search
- Hybrid keyword and vector search with the blending and reranking described above, and no external reranking model in any run shown here. BEAM ran on a simpler configuration of the same search.
- Readers and judges
- GPT-6 Luna reads and judges LongMemEval, LoCoMo and MemConflict, the reader at high reasoning effort, and GPT-5.6 Luna does both for BEAM. LongMemEval and MemConflict use their own judge prompts and LoCoMo and BEAM the prompt Mem0 publishes, which is how the other systems report them. Nothing in the reader's instructions names a benchmark question or its answer.
- Published numbers
- From each vendor's own write-up. We did not re-run them. Our benchmark harness is not public.
Benchmarks and published resultsLongMemEval ↗LoCoMo ↗BEAM ↗MemConflict ↗Mem0 research ↗gbrain-evals ↗